We make machines sound like they mean it
Flabbergasted is a small team of engineers, linguists and sound people building voices that listen first and answer in the time it takes to breathe.
2022
Founded in Stockholm
38
People across four cities
120
Languages and accents
4B
Characters voiced every month
What we hold ourselves to
Three rules that settle most arguments in the office.
Consent first
No voice gets cloned without a recorded yes from the person it belongs to. Every clone carries a watermark.
Latency is a feature
If a reply takes longer than a breath, it feels like a machine. We ship nothing that makes us slower.
Ship the boring parts
Billing, logs, retries and docs get the same care as the voices. That is what makes it work in production.
The people behind the voices
Linguists, audio engineers and a few people who just really like talking.
Meet the team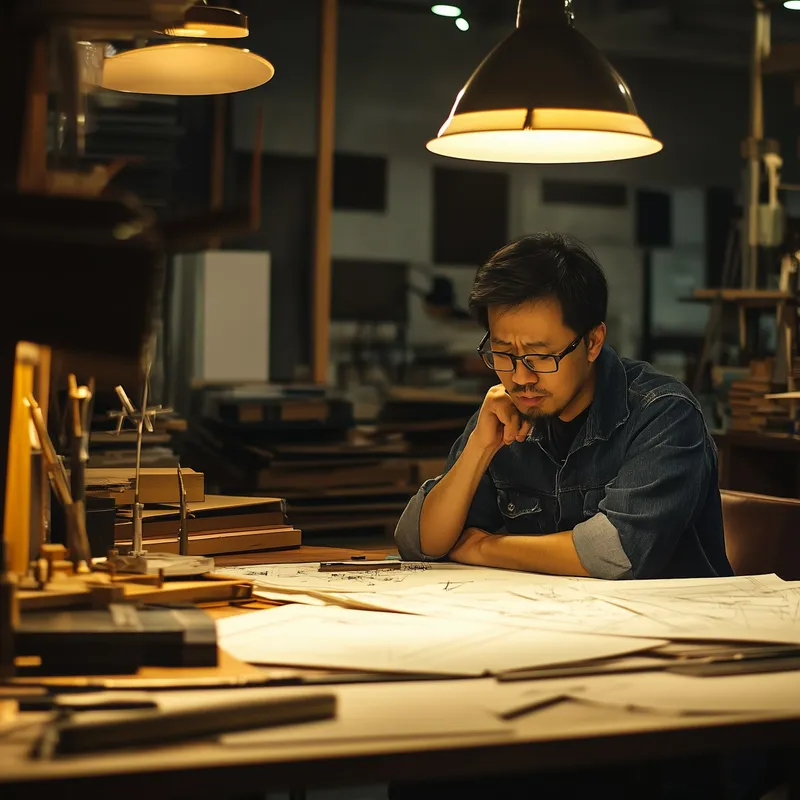
Marco Bianchi
Head of Speech Research
Leads the team training our voice models, with a soft spot for prosody and a hard line on anything that sounds robotic.
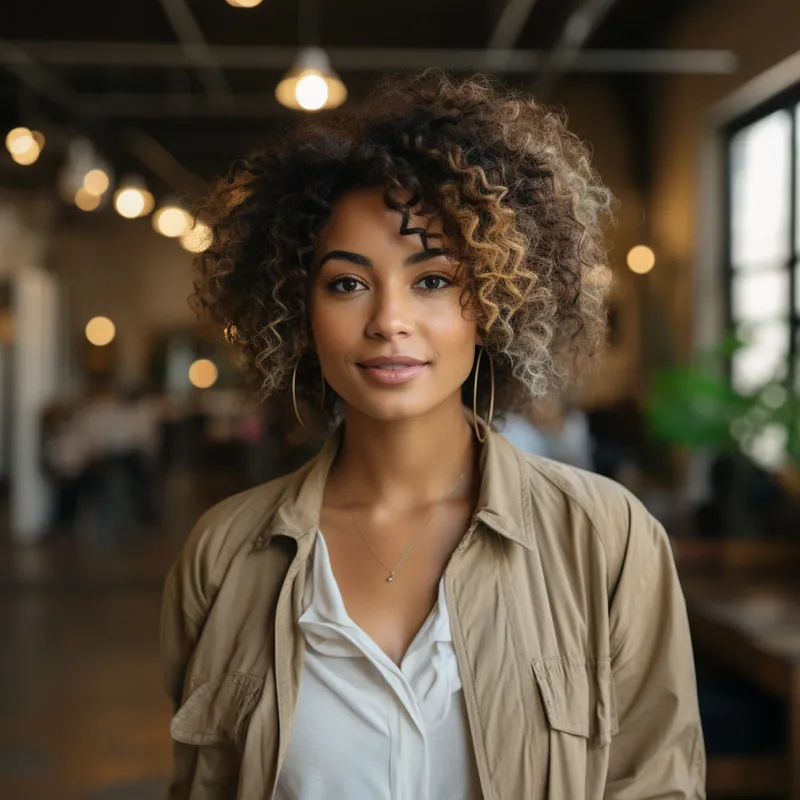
Maya Lombardi
Voice Content Writer
Writes the scripts in our demos and docs, and teaches customers how to write for the ear instead of the eye.
Backed by people who bet on sound
$42M raised from funds and founders who have shipped audio, telephony and developer tools themselves.
Halden Ventures
Series A lead
Rocca Partners
Series A
Nordfjell Capital
Seed lead
Vesta Seed
Pre-seed
Arvo Fund
Seed
Lindqvist & Co
Angel